Key takeaways
- Alpha Compute operates a 72-node Nvidia Blackwell cluster with InfiniBand networking and direct liquid cooling in St. Louis.
- Hardware partner Dell Technologies provides managed services below and above the operating system to maintain cluster uptime and meet SLAs.
- The neocloud deployment model pairs bare-metal sovereign infrastructure with public clouds to support sensitive AI training and inference.
- Alpha Compute secured an $81.7 million four-year compute contract and executed a $31.9 million non-recourse loan facility backed by Nvidia B300 hardware.
Specialized AI cloud providers, or neoclouds, are expanding rapidly to supply dedicated GPU capacity for AI labs and enterprises. However, maintaining reliable uptime on high-density accelerator clusters requires deep hardware-level managed services support. Speaking at the Dell Technologies New York Symposium, SiliconANGLE reported, Tom Richer, executive vice president of Alpha Compute Corp., highlighted that emerging providers cannot independently staff complex GPU operations. Partnering with Dell Technologies for integrated managed services keeps Alpha Compute’s 72-node Nvidia Blackwell cluster in St. Louis operational while supporting sovereign AI workloads designed to meet strict privacy mandates.
Managed services anchor specialized AI clusters
As enterprise demand for generative AI training and inference escalates, neoclouds have emerged to provide dedicated, bare-metal GPU capacity where conventional hyperscalers face supply constraints or multi-tenant virtualization bottlenecks. Yet deploying thousands of cutting-edge accelerators inside high-density racks introduces unprecedented operational friction, from thermal management to high-speed interconnect stability.
According to Alpha Compute, relying on multiple disjointed vendors invites operational breakdowns. When hardware faults, thermal anomalies, or networking degradations occur, disparate suppliers often engage in finger-pointing rather than rapid remediation. To counter this vulnerability, Alpha Compute established an integrated partnership where Dell Technologies provides comprehensive managed services support. Joint engineering teams manage ticketing, on-site hardware maintenance, component replacements, and service returns under rigorous service-level agreements (SLAs).
While AI research labs currently contract Alpha Compute to manage the infrastructure stack below the operating system, enterprise clients typically demand higher-level software orchestration. Dell’s operational support enables the provider to support environments above the operating system as enterprise onboarding expands, ensuring consistent cluster health across deployments.
Sovereign infrastructure and the operational trinity
Alpha Compute pivoted into dedicated AI infrastructure after initial operations in digital assets, adopting a “sovereign by design” architecture. This operational model pairs hardware from Dell Technologies and Intel Corp., which continues expanding its data center footprint with accelerators like the GPU D270 for inference, to establish hardware-enforced confidential computing enclaves down to the silicon level. By ensuring that training datasets and model weights remain within sovereign geographical borders, the architecture addresses compliance requirements under the European Union AI Act and the General Data Protection Regulation (GDPR).
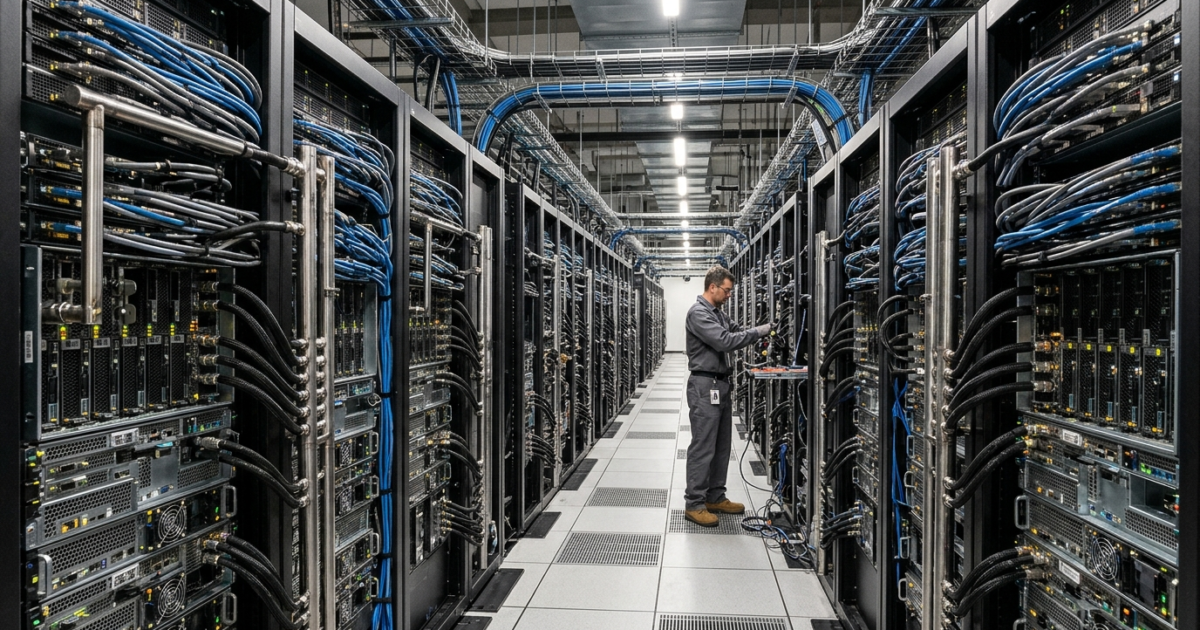
The provider’s production deployment in St. Louis features a 72-node cluster integrating Nvidia Blackwell server platforms delivered by Dell, interconnected through an InfiniBand network fabric, and chilled via direct liquid cooling in a retrofitted brownfield facility. Richer noted that sustainable cluster scaling depends on an operational trinity: securing a reliable off-taker, obtaining land and shell capacity, and delivering adequate power.
Capital requirements for such deployments are substantial. Alpha Compute recently executed a binding term sheet for a $31.9 million non-recourse loan facility secured directly by Nvidia B300 hardware assets and facility expansion assets. This hardware-backed financing follows an $81.7 million, four-year AI compute contract, demonstrating commercial off-taker validation for dedicated capacity.
Hybrid deployment alongside hyperscale clouds
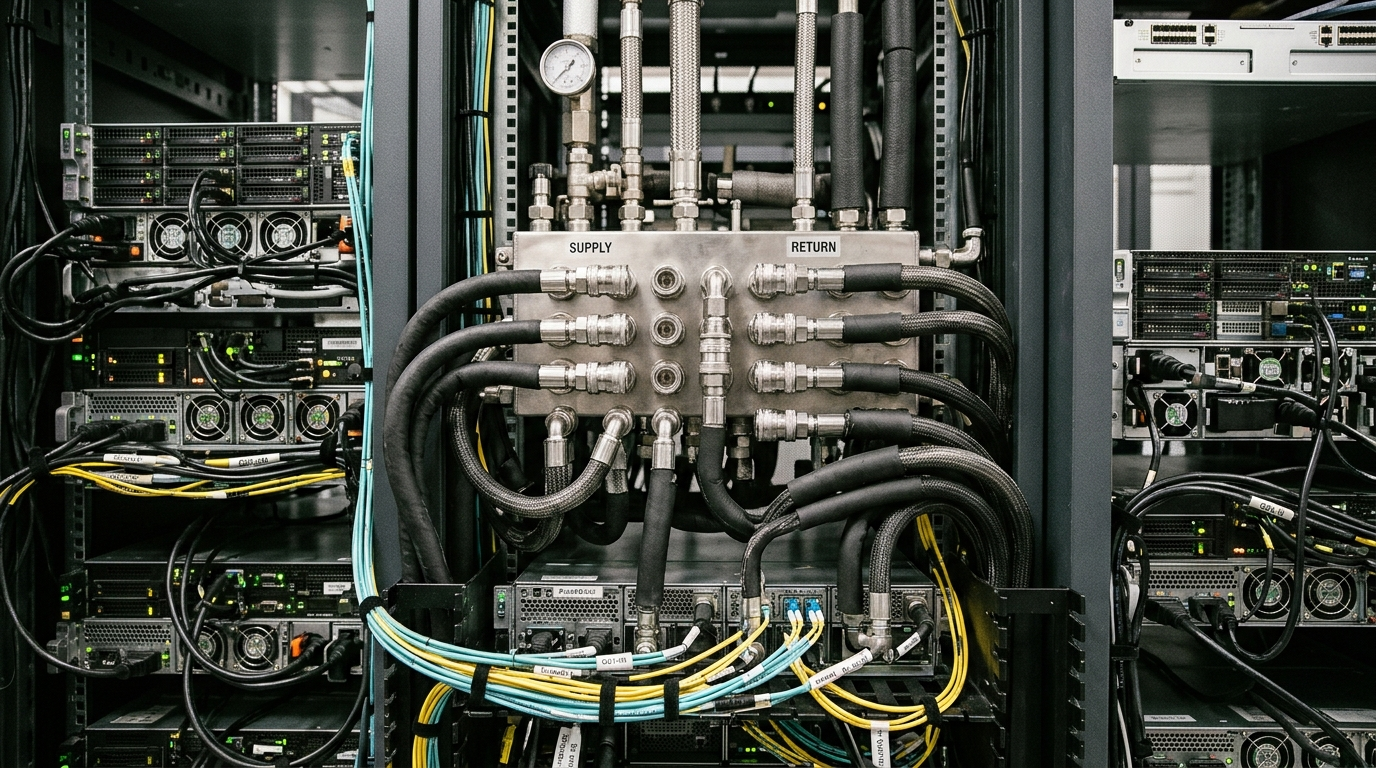
The architectural distinction between public hyperscalers and dedicated neoclouds centers on tenancy and fabric optimization. Rather than aiming to displace established public clouds, specialized providers position their clusters as dedicated extensions for latency-sensitive, high-throughput compute workloads.
Traditional hyperscalers utilize virtualized multi-tenant environments that risk noisy-neighbor contention and shared network bottlenecks. In contrast, specialized GPU clouds differentiate by delivering bare-metal isolation, non-blocking InfiniBand or RoCE interconnect fabrics, and dedicated physical nodes. This setup accommodates superintelligence workloads and large-scale model training that cannot tolerate virtualization overhead.
| Infrastructure Dimension | Hyperscale Public Cloud | Specialized Neocloud (Alpha Compute Model) |
|---|---|---|
| Compute Tenancy | Virtualized multi-tenant instances with resource sharing | Dedicated bare-metal nodes with zero noisy-neighbor interference |
| Interconnect Fabric | Standardized software-defined or virtualized overlay networking | High-bandwidth, non-blocking InfiniBand fabric optimized for distributed training |
| Thermal Architecture | Standard data center perimeter cooling with selective liquid cooling | Direct liquid cooling retrofitted for dense accelerator racks |
| Operational Management | Standardized self-service IaaS with tiered support ticketing | OEM hardware partner integrated managed services below and above the OS |
| Data Governance | Multi-region global cloud domains requiring complex sovereign policy layers | Sovereign-by-design silicon enclaves and in-country data residency |
Industry research from William Blair notes that the rise of neoclouds represents a structural shift across cloud architecture. The intense thermal and networking demands of generative AI workloads necessitate purpose-built infrastructure where hardware vendors actively participate in lifecycle maintenance.
What happens next
Alpha Compute plans to commission additional Nvidia Blackwell clusters as new hardware tranches and data center space come online. The company’s expansion roadmap tests whether hardware-secured debt facilities can reliably sustain high-density infrastructure rollouts ahead of commercial revenue capture.
For Dell Technologies, managing operations for neocloud providers reinforces its enterprise AI factory strategy. By embedding managed services directly into emerging cloud operators, original equipment manufacturers secure a pivotal operational foothold across both sovereign enterprise data centers and specialized high-performance AI clouds.
Sources
- Managed services support keeps neocloud GPU capacity healthy
- Alpha Compute Executes Binding $31.9 Million Non-Recourse GPU Financing Backed by NVIDIA B300 Hardware Assets
- Alpha Compute signs $81.7M four-year AI compute contract – Investing.com
- What Is a Neocloud? The GPU Clouds Powering the AI Boom – Decrypt
- Understanding Neocloud offering GPU-as-a-Service (GPUaaS)
- The Rise of Neoclouds: Powering the Next Phase of AI | William Blair