Key takeaways
-
- Current advances in large language and vision models do not transfer directly to physical movement, where machines face the infinite variability of the physical world.
- Robotics researchers emphasize that bipedal humanoid form factors are not synonymous with general-purpose intelligence or autonomous utility.
- Tensions have emerged across robotics labs between scaling existing foundation models and developing fundamentally new physical architectures.
- Lab demonstrations often rely on scripted routines or teleoperation, masking steep hurdles in real-world contact mechanics, safety, and physical reliability.
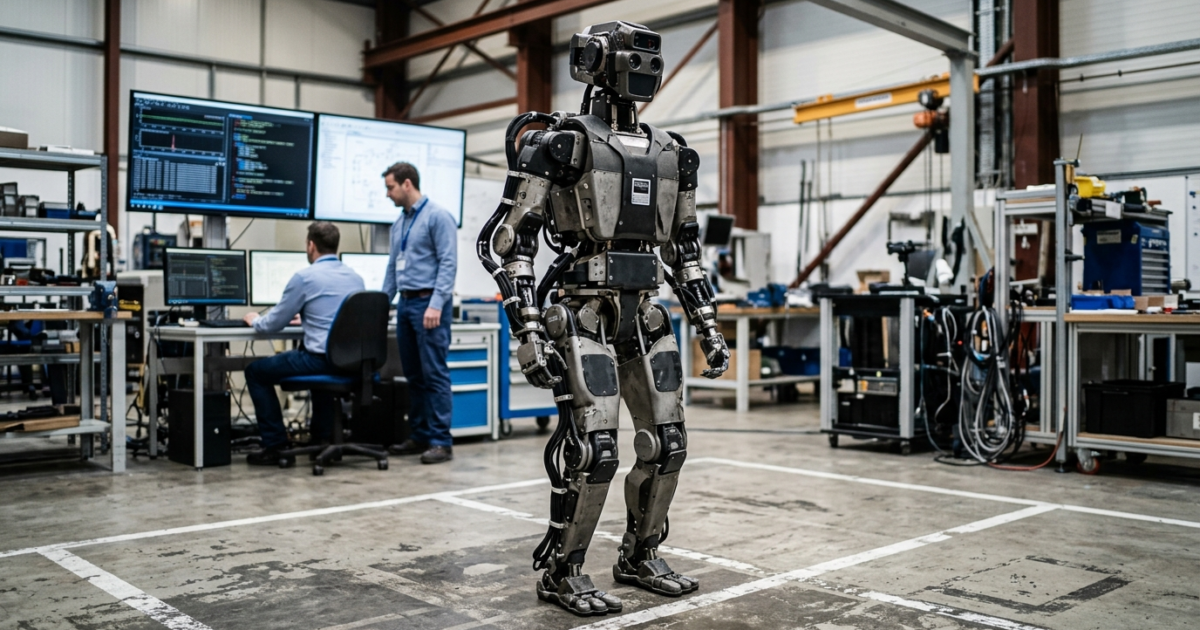
Breakthroughs in generative artificial intelligence will not translate into practical, general-purpose humanoid robots in everyday life any time soon. While modern architectures powering chatbots like ChatGPT and Claude handle text tokens and static visual representations with notable fluency, applying that software paradigm to embodied machines reveals acute limitations. Robotics researchers emphasize that training an intelligence on digital language and two-dimensional images cannot easily master the infinite variability, contact mechanics, and continuous dynamics of the physical world. Furthermore, conflating bipedal morphology with generalist utility is fundamentally misleading. Across major research laboratories, engineers remain sharply divided over whether scaling existing foundation models is sufficient or if physical agency requires an entirely distinct technological foundation.
The Physical Reality Gap: Language Models Versus Physical World Dynamics
Much of the recent surge in humanoid robotics investment stems from an intuitive but unproven hypothesis: if deep transformer models can learn the grammar of human speech, they should also be able to learn the grammar of human movement. According to an analytical report published by MIT Technology Review in collaboration with the research foundation Aventine, leading roboticists caution that this assumption vastly oversimplifies physical reality.
Large language models operate in discrete, symbolic spaces. When a model predicts the next token in a paragraph, a low-confidence guess or minor hallucination causes minimal operational damage. In physical robotics, however, actions take place in a continuous, non-linear environment governed by unforgiving physical laws. A controller attempting to place a fragile glass on a counter must manage micro-adjustments in friction, normal force, surface compliance, and center-of-mass shift across millisecond intervals. An error margin of two millimeters or fifty milliseconds can shatter an object or throw a multi-kilogram machine off balance.
The core issue rests on data distribution. Large foundation models succeed because the internet contains trillions of high-quality text tokens and billions of tagged images. By contrast, real-world physical interaction data is scarce, expensive, and difficult to standardize. Gathering physical sensorimotor telemetry requires operating physical hardware in real time or generating synthetic data in simulators. Yet simulations struggle with the notorious “sim-to-real” gap, failing to capture subtle variables such as joint backlash, thermal expansion in actuators, cable stretch, and erratic contact dynamics. As a result, systems trained purely on abstract representations struggle when faced with messy, unscripted domestic or industrial surroundings.
Form Factor Confusion: Why Bipedal Humanoids Are Not Generalist Machines
One of the persistent conceptual errors in the current market cycle is treating humanoid morphology as proof of general-purpose utility. Promoters frequently argue that because human civilization was engineered around human dimensions—stairs, doorways, workbenches, and hand tools—a bipedal robot with two arms is the natural shape for generalist work. However, mechanical engineers point out that physical form factor and algorithmic generalization are entirely separate problems.
A bipedal structure is inherently unstable. Maintaining static and dynamic balance on two feet requires constant active stabilization, draining battery capacity and adding failure points across dozens of high-torque actuators. In structured industrial environments, wheeled bases, quadrupeds, or dedicated gantry arms routinely offer superior payload capacity, energy efficiency, and mechanical reliability. Constructing a machine with two legs does not make its control software capable of reasoning through diverse tasks; it merely imposes extreme stabilization overhead on the compute platform.
True generalization resides in the cognitive and perceptual stack, specifically the ability to generalize across novel objects, shifting spatial arrangements, and ambiguous task specifications. A robot that can walk across a showroom floor during a scripted keynote demonstration is not demonstrating general autonomy; it is executing a localized balance routine. Confusing anatomical imitation with cognitive adaptability risks misdirecting billions of dollars into complex hardware packages that lack the underlying spatial reasoning necessary to perform productive labor.
Capability Versus Demonstrated Evidence in Modern Robotics Labs
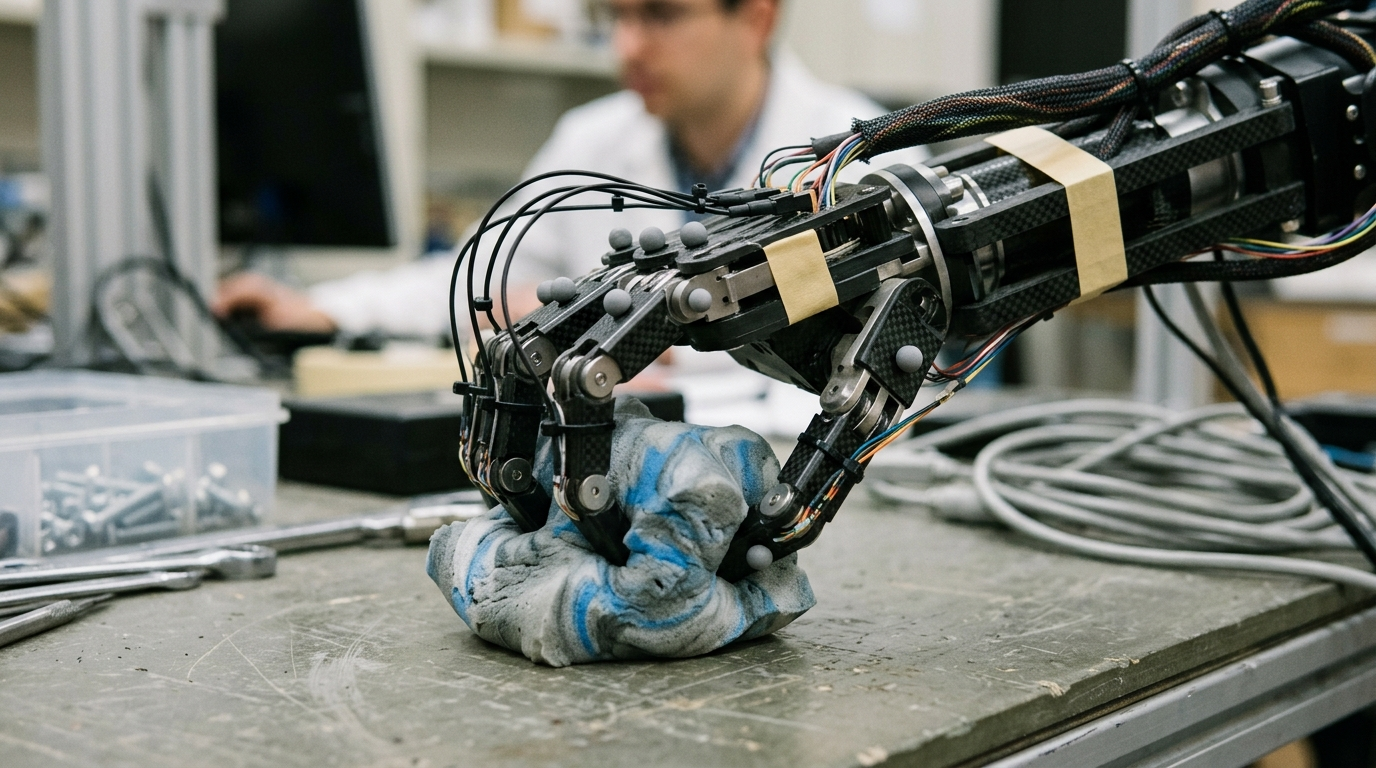
Assessing the practical timeline for autonomous humanoids requires distinguishing between controlled demonstrations and unstructured field performance. Viral videos shared across social media frequently obscure human teleoperation, heavy cherry-picking, and carefully orchestrated lighting and prop positioning.
| Robotic Domain | Demonstrated Lab Performance | Controlled Test Conditions | Real-World Operational Reality |
|---|---|---|---|
| Bipedal Locomotion | Dynamic walking, squatting, and navigating flat ramps or uniform steps. | Pre-scanned geometric surfaces, consistent lighting, and absence of external physical disturbances. | Irregular outdoor terrain, slippery spills, shifting rugs, and unpredictable moving obstacles destabilize dynamic balance controllers. |
| Object Manipulation | Picking rigid geometric shapes, sorting battery cells, or placing cups in designated slots. | Identical object dimensions, pre-trained visual contrasts, and repeatable grasp orientations. | Deformable fabrics, transparent glassware, greasy surfaces, and varying weights require high-frequency tactile feedback that current vision systems lack. |
| Instruction Grounding | Parsing natural language prompts (e.g., “pick up the red block”) into sequential action primitives. | Constrained semantic dictionaries and structured workspaces where objects match clear visual categories. | Ambiguous human intent, spatial occlusion, and multi-step tasks demand complex contextual reasoning under hard real-time latency limits. |
| Safety & Compliance | Operating alongside lab engineers wearing emergency-stop pendants or tethered to overhead harnesses. | Cordoned staging areas with controlled human proximity and low operating velocities. | Deploying 70-kilogram steel-and-aluminum machines near children, pets, or workers requires certified failsafes and physical collision compliance. |
As the table illustrates, the distance between laboratory benchmark achievement and unassisted field operation remains wide. Unlike pure software agents, physical robots face harsh operational constraints: hardware wear, sensory degradation, motor heating, and immediate physical consequences whenever perception errors occur.
The Engineering Divide: Scaling Existing Models Versus Architectural Reboots
Inside research institutions and commercial robotics teams, two distinct schools of thought have formed regarding how to bridge this gap.
The first camp advocates for scaling vision-language-action (VLA) foundation models. Proponents argue that by aggregating larger cross-embodiment datasets—such as multi-institution robotic manipulation logs—and increasing parameter scale, models will develop emergent spatial understanding. Under this approach, teleoperation fleets operated by human workers collect millions of task demonstrations. Neural networks then use imitation learning and behavioral cloning to predict continuous end-effector trajectories directly from camera feeds. Advocates maintain that foundation models will internalize physics implicitly, just as language models internalized semantic logic.
The skeptical camp, which includes many classical roboticists and control theorists, contends that behavioral cloning cannot solve the long tail of physical edge cases. Because neural policies lack verifiable causal models of the physical world, minor deviations from training distributions can trigger catastrophic action loops. When an autonomous system encounters an unfamiliar angle or an unobserved friction coefficient, it cannot rely on statistical interpolation. Critics argue that real physical autonomy requires explicit world models, integrated physics simulators, and hybrid architectures that combine classical feedback control with symbolic reasoning.
This divide also intersects with broader corporate risk debates. While tech leadership often maintains that software deployment can tolerate trial-and-error cycles (as Sam Altman has argued regarding AI safety trade-offs), physical robots introduce kinetic hazards that software sandboxes never face. A hallucinated code snippet produces a compiler error; an erroneous joint torque command can destroy proprietary factory equipment or inflict severe physical injury on nearby personnel. Consequently, enterprise risk tolerances for embodied autonomy are orders of magnitude stricter than those for text-generating software.
Bottom line
Enterprise buyers and technology leaders should separate promotional marketing from deployable reality when assessing humanoid robotics. While generative AI has accelerated high-level task planning and semantic scene recognition, it has not resolved the fundamental challenges of physical embodiment, closed-loop tactile feedback, and unpredictable contact mechanics. Bipedal humanoid machines remain expensive, fragile research platforms that are years away from executing unassisted, cost-effective work in homes or unstructured enterprise facilities. For organizations seeking automation today, specialized kinematic designs, autonomous mobile bases, and fixed manipulators will continue to outperform general-purpose humanoid forms across virtually every practical metric.