Key takeaways
- benchmark tasks on 15 databases, the model beats expert-tuned gradient-boosted trees by nearly 4 AUROC points on RelBench V1 and exceeds XGBoost by 7 to 13 MRR points on SAP SALT.
- Trained entirely on synthetic relational data via the PluRel framework, the model scales to schemas with over 500 billion rows and is accessible via Python or NVIDIA NIM microservices.
NVIDIA Kumo Relational is a pre-trained relational foundation model designed to run in-context predictive inferences directly on enterprise databases without manual feature engineering, table flattening, or task-specific model training. Built to address business predictions such as customer churn, fraud detection, and demand forecasting, the model reads up to 10,000 historical context examples at inference time to compute target variables in a single forward pass. Across 41 benchmark tasks on 15 databases, NVIDIA reports that Kumo Relational beats expert-tuned gradient-boosted decision trees and supervised deep learning models while scaling across schemas containing over 500 billion rows.
The Shift From Feature Pipelines to In-Context Relational Models
Production predictive modeling on enterprise databases has historically relied on an engineering-heavy workflow. When machine learning teams want to predict which customer will churn or which invoice will be paid late, the underlying data rarely lives in a neat, single table. It resides across relational database management systems and cloud data warehouses, divided into transactional tables, user dimensions, and event logs linked through foreign keys and timestamps.
To feed this data into standard machine learning algorithms such as XGBoost, LightGBM, or CatBoost, data science teams must collapse complex entity-relationship graphs into a single tabular row per entity. This manual feature engineering process—computing rolling 30-day aggregations, count metrics, average order values, and interaction statistics—often demands weeks of developer time. Moreover, flattening structured data discards temporal nuances and subtle multi-hop graph relationships that exist across table boundaries.
Kumo Relational approaches structured enterprise data the way large language models approach text: as an in-context learning problem. Rather than retraining a dedicated model for every individual business task, users define the predictive objective using Predictive Query Language (PQL). PQL provides a declarative interface where developers specify what to predict rather than how to extract features. The model then loads relational subgraphs and historical target outcomes directly as context examples, computing new predictions in a single forward pass without modifying underlying model weights.
Inside the Architecture: Within-Table and Across-Table Attention
Processing raw relational databases with deep neural networks introduces severe computational hurdles. Naively running self-attention over every cell across multiple interconnected tables causes quadratic computational growth that quickly overwhelms GPU memory. According to technical documentation in the KumoRFM-2 research paper, the system resolves this bottleneck through a decoupled, two-stage attention architecture that separates table-level processing from cross-table graph reasoning.
The workflow operates through three coordinated processing phases:
- Automated Context Generation and Leakage Prevention: When a PQL query is submitted, the system reconstructs historical database states. For temporal tasks, it samples entity-centric subgraphs anchored at historical timestamps. Ground-truth targets are derived from events occurring after the anchor timestamp, while the model is strictly served data recorded prior to that timestamp. This mechanism guarantees that future target information cannot leak into historical context representations.
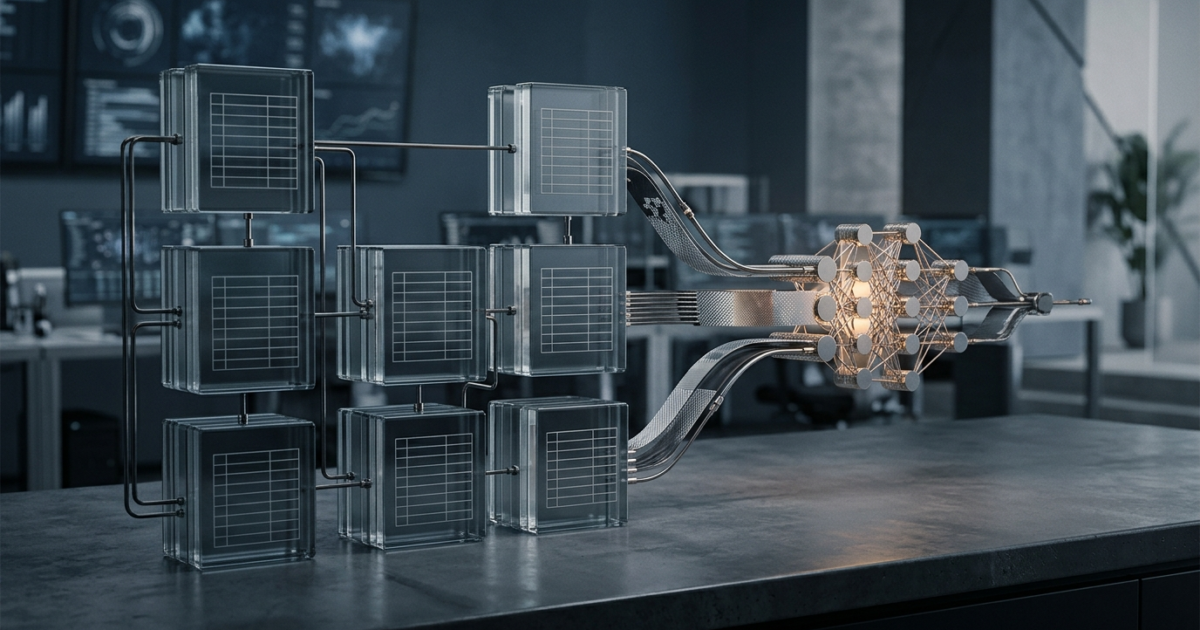
- Reasoning Within Tables: A lightweight neural network processes each database table independently. It alternates between column attention, which correlates values and distributions within a single column, and row attention, which captures interactions among features in a single row. Context targets are injected early in this phase, allowing the network to identify which columns carry predictive signal for the specified objective and filter out noisy, uninformative attributes before representations leave the local table.
- Reasoning Across Tables: Once rows are encoded into dense embeddings, a larger network distributes these representations across the full relational schema. It applies graph attention over primary-key and foreign-key links, interleaved with cross-sample attention across up to 10,000 retrieved context examples. By operating strictly on row embeddings rather than individual data cells, the model avoids quadratic cost, enabling deep multi-hop relational traversal without prohibitive memory overhead.
Synthetic Pre-Training via the PluRel Framework
Foundation models for natural language and computer vision rely on massive public web crawls. However, enterprise relational databases are proprietary, privacy-restricted, and siloed behind compliance firewalls. Public relational datasets are far too scarce to pre-train a generalized foundation model.
To overcome this data scarcity, NVIDIA pre-trained Kumo Relational entirely on synthetic relational data using the PluRel framework (Kothapalli et al., ICML 2026). Developed in collaboration with Kumo researchers, PluRel systematically generates synthetic multi-table databases across three progressive stages:
- Schema Generation: Synthesizes diverse relational database schemas featuring realistic table hierarchies, cardinality ratios, and referential structures.
- Relational Graph Topology: Generates primary-key and foreign-key links between rows that reproduce the clustering patterns, hub-and-spoke distributions, and power-law degree distributions observed in real-world business schemas.
- Causal Column Generation: Populates columns using Structural Causal Models (SCMs) that simulate realistic cross-table dependencies, temporal trends, seasonal shifts, and non-linear interactions.
Because synthetic database generation is computationally lightweight, pre-training data volume is effectively unlimited. Research on PluRel confirmed that pre-training loss follows power-law scaling as more synthetic relational databases are introduced, with representation quality transferring directly to real enterprise benchmarks.
Empirical Performance Across RelBench, SAP SALT, and RelArena
NVIDIA evaluated Kumo Relational across 41 predictive tasks spanning 15 relational databases drawn from RelBench V1 and V2, SAP SALT, and 4DBInfer. The evaluation suite covered e-commerce, healthcare, enterprise resource planning, and academic datasets, none of which were present during synthetic pre-training.
On RelBench V1 classification tasks, Kumo Relational outperformed gradient-boosted trees trained on expert-engineered tabular features by an average of nearly 4 AUROC points out of the box. On the SAP SALT enterprise benchmark, it surpassed baseline XGBoost models by 7 Mean Reciprocal Rank (MRR) points in zero-shot evaluation and by 13 MRR points following task-specific fine-tuning.
The table below summarizes verified benchmark results and evaluation conditions documented in the release evidence:
| Evaluation Suite | Baseline System | Kumo Relational Metric | Evaluation Mode and Conditions |
|---|---|---|---|
| RelBench V1 Classification | Expert-Engineered GBDT / XGBoost | +4 AUROC points lead on average | In-context evaluation without task-specific training |
| SAP SALT Enterprise Benchmark | XGBoost with manual feature engineering | +7 MRR points (zero-shot) / +13 MRR (fine-tuned) | Outperformed AutoGluon tabular ensembles by 8% zero-shot, 16% fine-tuned |
| SAP SALT Enterprise Benchmark | Recent Tabular Foundation Models | ~25% MRR margin over competitors | Multi-table relational schema evaluation |
| RelArena-α Leaderboard | rt-plurel (Highest accuracy entry) | Elo 1,842 at ~17 seconds / 1,000 samples | rt-plurel scored Elo 1,878 but required ~7,300 seconds (~430× slower) |
| Data Scarcity Stress Test | Standard supervised baselines | High predictive stability down to 0.2% context | Sub-sampling test evaluated on limited training records |
| Schema Degradation Stress Test | Intact relational graph baselines | Robust performance with 75% FK links removed | Evaluated under missing referential constraints and noisy columns |
On the RelArena-α benchmark leaderboard, Kumo Relational established a position on the accuracy-efficiency Pareto frontier. While the top-scoring specialized research model, rt-plurel, recorded an Elo rating of 1,878 compared to Kumo Relational’s 1,842, rt-plurel required approximately 7,300 seconds per 1,000 samples. In contrast, Kumo Relational completed 1,000 sample inferences in 17 seconds, delivering competitive accuracy roughly 430 times faster.
Deployment Architecture and Architectural Boundaries
For engineering teams evaluating production adoption, NVIDIA offers two deployment pathways through its open-source structured-data-models library:
- Local In-Memory Execution: Python developers can import the model directly using PyTorch and CUDA. Weights are downloaded from the Hugging Face Hub repository under the OpenMDW License Agreement version 1.1, while supporting code is distributed under the Apache 2.0 license. A custom graph execution engine utilizes memory-mapped I/O at transfer speeds up to 5 GB/s, enabling context sampling from databases housing more than 500 billion records.
- Microservice Architecture via NVIDIA NIM: Organizations can deploy the model as a self-contained containerized microservice and interact with it using the structured-data-models-client. Autonomous software agents and automated data pipelines query the endpoint using declarative PQL expressions, allowing agents to anticipate downstream business outcomes without human data science intervention.
Despite these capabilities, technical architects must recognize specific architectural boundaries. First, the model relies on relational depth and temporal sequences; flat, single-table datasets with static rows offer limited leverage for its graph attention layers. Second, in-context learning context windows are bounded at 10,000 historical examples in standard benchmark configurations. When organizations possess millions of labeled training instances for a single stationary problem, dedicated supervised pipelines or fine-tuned foundation models can still match or exceed raw in-context accuracy. Finally, graph traversal requires predictive signals to lie within a manageable number of relational hops from the target entity, meaning broad enterprise schemas must still be scoped to relevant table clusters.
Bottom line
NVIDIA Kumo Relational introduces an architectural transition for enterprise machine learning by demonstrating that relational foundation models can match or outperform expert-crafted gradient-boosted trees without requiring manual feature engineering. For enterprise IT and AI platform leaders, the primary value lies in operational agility: replacing weeks of pipeline development with declarative predictive queries. However, production readiness hinges on database connection latency, schema stability, and whether an organization’s prediction problems fit within bounded multi-hop subgraphs and 10,000-sample context windows.
Sources
- NVIDIA Kumo Relational Outperforms Supervised Machine Learning on Relational Data, No Training Required
- [2604.12596] KumoRFM-2: Scaling Foundation Models for Relational Learning
- nvidia/Kumo-Relational · Hugging Face
- GitHub – NVIDIA/structured-data-models: Foundation Models for Structured Data · GitHub
- [2602.04029] PluRel: Synthetic Data unlocks Scaling Laws for Relational Foundation Models
- [2602.09572] Predictive Query Language: A Domain-Specific Language for Predictive Modeling on Relational Databases
- GitHub – NVIDIA/structured-data-models-client: One Python client for NVIDIA’s structured-data foundation models: ask a predictive question of one table or of a whole relational schema, and get an answer without training anything. · GitHub